

NVIDIA GB200 NVL72 Infrastructure and MPO-8 APC Cabling for Scalable Units
Deconstructing the cabling architecture of a Blackwell Scalable Unit (SU), where 8 racks converge into 9,216 active fibre strands.
The DGX GB200 Scalable Unit (SU) represents a big shift in data centre architecture. The SU is a unified 576-GPU entity interconnected by 9,216 active fibre strands. ScaleFibre provides the precision-terminated trunks required to manage this density.
The 4 Physical SuperPOD Fabrics
NVIDIA segments the SU into distinct physical layers to isolate GPU traffic.
MN-NVL (NVLink 5)
Scale-UpThe ‘internal’ rack network connecting 72 GPUs at 1.8 TB/s.
- Zero Optical Fibre
- Passive Copper Backplane
- Blind-mate connectors
Compute InfiniBand
Scale-OutThe primary ‘East-West’ fabric for massive multi-node training.
- 4,608 active fibres per SU
- Rail-optimised topology
- Quantum-3/Quantum-2
Storage & In-Band
FrontendEthernet-based fabric for high-speed data ingestion and provisioning.
- 5:3 Blocking factor
- BlueField-3 DPU offload
- VXLAN/RoCE support
OOB Management
Control PlaneThe isolated network for hardware telemetry, BMC, and PDU management.
- RJ45/Cat6 Copper
- SN2201 Switch tier
- Physical air-gap security
Exascale SU Metrics
An 8-rack Scalable Unit represents the fundamental building block of the NVIDIA AI Factory.
9,216
Active Fibres per SU4,608
Compute-Only Strands5:3
Storage Blocking Ratio400G/800G
Native Port Speeds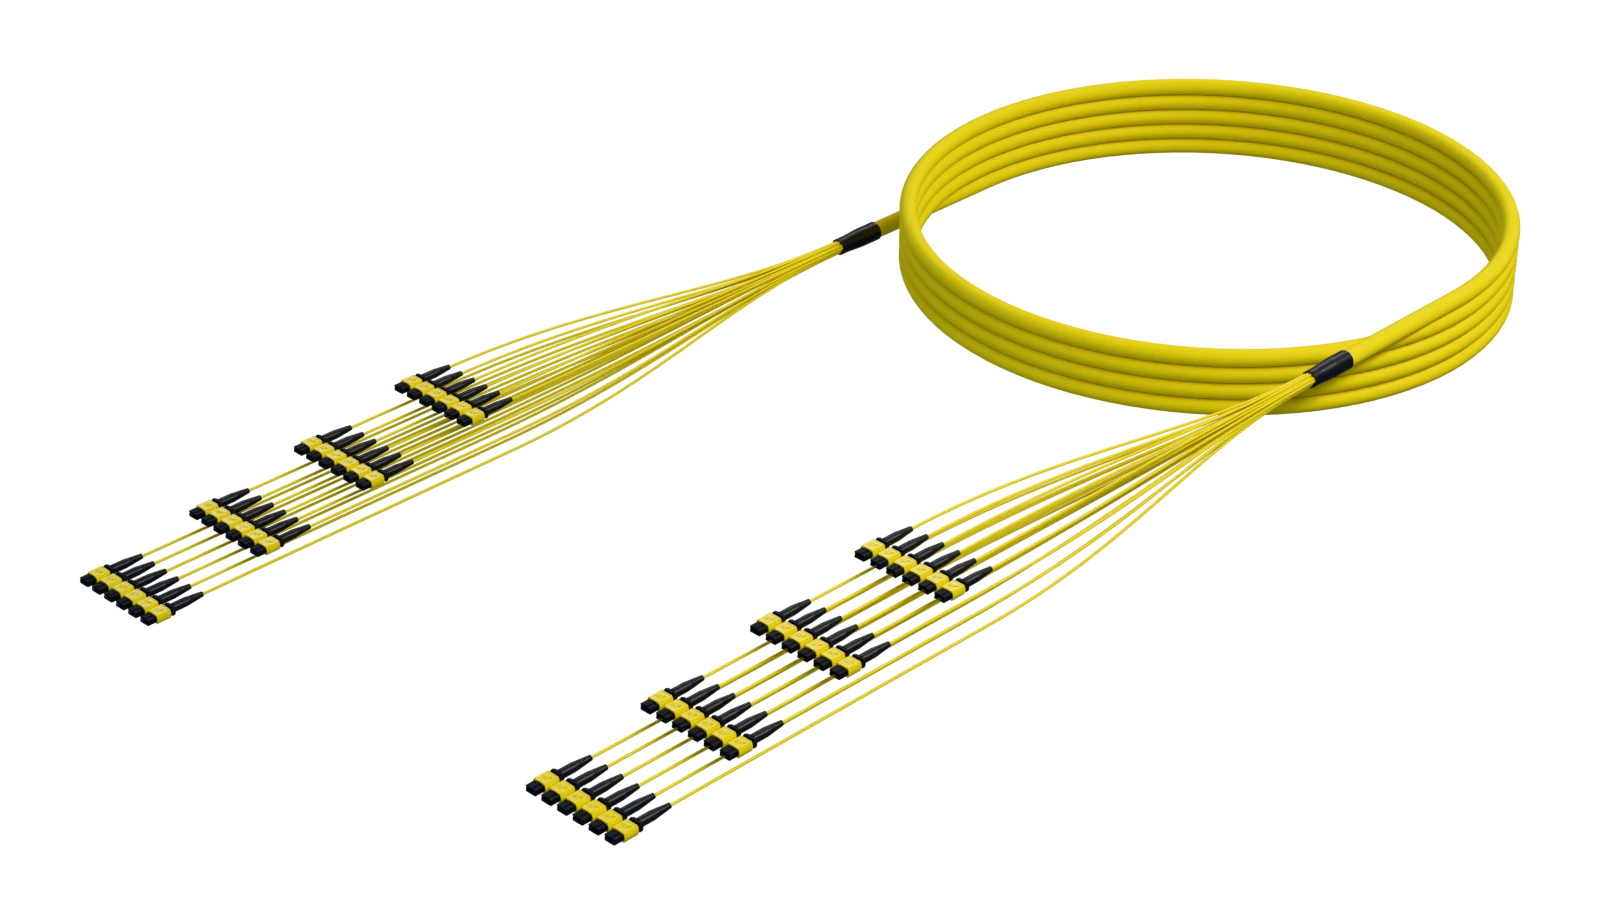
High Fibre Count MPO Trunk Cables
High fibre-count MPO trunk assemblies with 48 to 576 fibres. Enables fast, large-scale deployment with reduced labour and minimal installation overheads.
View High Count MPO Trunk DetailsThe Three Levels of SU Connectivity
Level A: Server-to-Leaf
1,152 fibres per rack using high fibre count trunks or jumpers to connect NVL72 nodes to Leaf Switches.
Level B: Leaf-to-Spine
Aggregating rail-aligned traffic within the SU using 1:1 non-blocking links for compute.
Level C: Spine-to-Core
Scaling beyond the SU to a centralised Core area using high-count trunks.
Legacy Patching (Point-to-Point)
- ✕Manual Complexity: Requires individual patch cords for 9,216 fibres per 8-rack block.
- ✕Airflow Obstruction: Dense cable bundles block liquid-cooling exhaust paths.
- ✕Risk Profile: High probability of ‘crossed rails’ during manual 1:1 patching.
- ✕Deployment Time: 115+ hours for manual routing and labelling per SU.
Modular High Fibre Count Trunking
- ✓Plug-and-Play: Consolidates thousands of fibres into pre-terminated 128F/144F/256F/288F/576F tailored trunks.
- ✓Thermal Optimisation: Small-diameter cables maximise airflow in dense racks.
- ✓Pathway Efficiency: Consolidates 1,152 active fibres per rack into high-count MPO backbones.
- ✓Installation Profile: Rapid deployment via pre-terminated factory-tested assemblies.
Active Fibre Growth: Node to Full SuperPOD
Cabling ComplexityScalable Unit Visualised
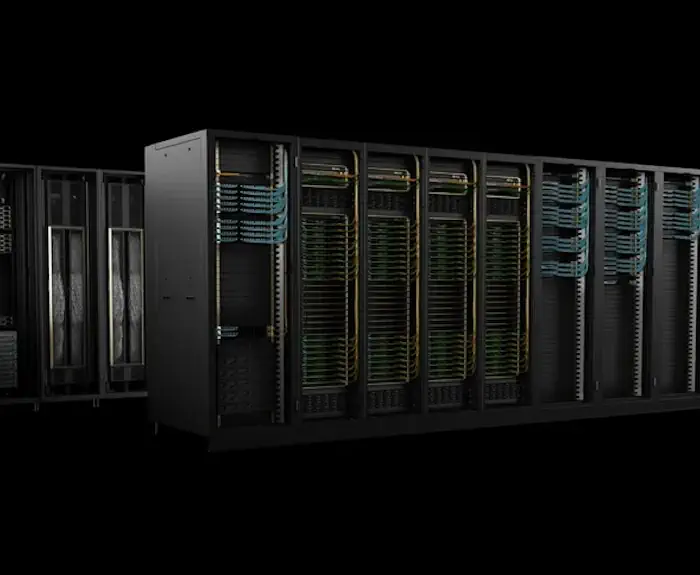
The 8-Rack Compute Block
An NVIDIA GB200 SU (Scalable Unit) consists of 8 racks, each housing a DGX GB200 NVL72 system with 72 GPUs.
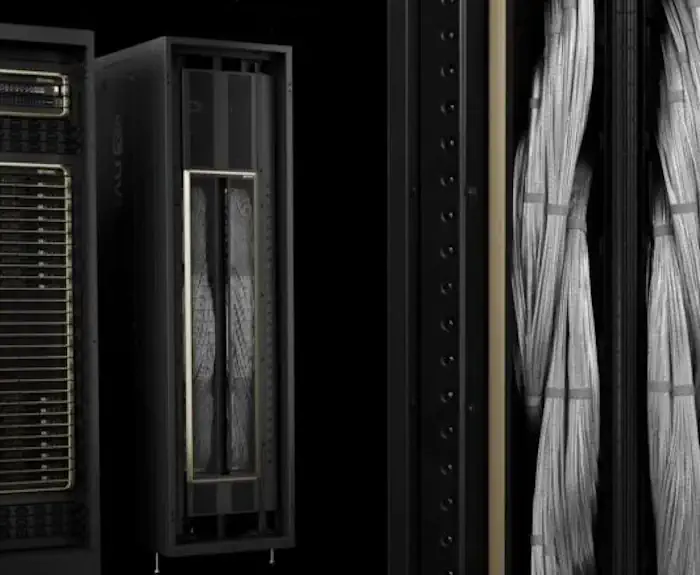
High Fibre Count Trunk Distribution
Consolidating thousands of rack fibres into high-density trunks for airflow clearance, rapid installation and minimal pathway usage.
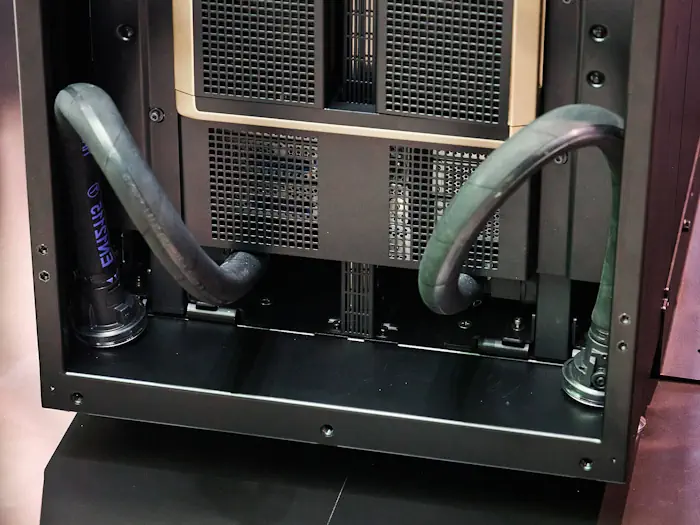
Liquid Cooling
Liquid-cooled cold plates stabilise the tray environment, allowing OSFP transceivers to shed heat effectively via riding heat sinks.
Technical FAQ
Architect Your AI Factory
ScaleFibre delivers pre-terminated cabling solutions for NVIDIA DGX SuperPOD deployments.
Get in TouchGet details on high fibre count trunks for your NVIDIA DGX SU.